I am writing this after the first stretch of 2-3 weeks in ~6 months in which nothing crashed and nothing went unreachable (other than inevitable circumstances). The whole cluster is described in a Git repo now, every service is behind Traefik with real certificates, and I can rebuild the server from scratch if the disk dies. Mostly.
Getting there involved a lot of nights that were not like that. An early one went like: the cloudflared logs said connected. The Pods said running. The browser said nothing at all. Turns out everything was working as intended which also included the firewall which was just quietly dropping all incoming requests by default.
This is an ongoing journey, so I thought I would write it down as I go, partly as a record of how and why I got into self-hosting and Kubernetes, and partly in case it saves someone else a few hours. I have split this post into three parts: Why, What, and How.
Why? (The Motive)
The Short Version:
I have a Laptop with a dying screen, i wanted to ensure that i dont add to the e-waste bin just yet and these streaming services are and were annoying to use with day on day more restrictions and cost hikes.
The Longer Version:
This can be divided into 4 parts:
Cost and annoyance.
I was paying around ₹400 a month across a few services, and none of them could play the media I already owned. Worse, the ones I did pay for kept removing things. A show I was halfway through would vanish, I’d go hunting for wherever it had moved to, and the answer was usually another subscription. Pay, lose access, pay somewhere else, then the cycle continues again and again.
Renting a VPS to run this instead would have put me right back where I started, a monthly bill in the same range as the subscriptions I was trying to cancel, Old hardware on the other hand just costs me electricity monthly.
Learning by Doing
I Started my career as a pentester, i am used to breaking things and wanted to do something different, i wanted to create/build something for a change, so I started on Kubernetes, Git and CI/CD, and worked toward the CKA.
I don’t retain anything I’m not actively using. Reading about Deployments and Services gets me to the end of the page and no further. So I do it backwards: pick something I actually want, write down what it has to do, and build until it does that. Jellyfin on my own hardware was the requirement. Everything else in this post is what it took to meet it, and every time I learned something new, it went straight into the cluster if it made the existing setup better.
Security
So far my career has been security engineering alongside a DevOps team, which means I’ve spent it on the reviewing side of the wall. I know what the failure looks like, telnet reachable from the internet, a web app happily serving over plaintext, a cert nobody renewed. What I’d never done is be the person who has to fix it, on a deadline, without breaking the thing that’s already running.
That gap bothered me. It’s easy to write a finding that says “enforce TLS on all endpoints” and never learn that the hard part isn’t the enforcing, it’s the renewal, the redirect chain, and the one internal service that breaks when you turn it on. I wanted to build the thing I usually audit, so that next time I can hand over a solution instead of a problem.
Also, bragging rights.
Hardware
The laptop is an HP Pavilion 15 Gaming that I got when I started college, 16 GB of RAM, a GTX 1050, a 2 TB WD Black SSD and a 1 TB HDD of unknown parentage. It was a pain in the ass for most of its life, but it was my pain in the ass, and when the screen started dying and I replaced it with a desktop, throwing it out felt wrong.
It also turned out to be a better fit for the job than I expected. I let jellyfin transcode on the integrated Intel GPU instead of the GTX 1050 due to the 1050 giving me head aches, Quick Sync handles everything I throw at it, it doesn’t need a proprietary driver kept in lockstep with kernel updates, and it sips power on a machine that’s on all day. That leaves the 1050 free for work that actually wants CUDA: Blender renders, or a small LLM I can point at from the rest of the cluster. Two GPUs, two jobs, neither fighting the other for a machine that’s on 24/7 anyway. 16 GB is more RAM than a single-node k3s cluster serving video to one household will ever need.
So I turned it into a one-node cluster, set up so that adding a second node later would be a config change rather than a rebuild. The rest is this post.
But this is a Docker Compose job right?
Yes, Yes it is,
A docker-compose.yml with Jellyfin, a reverse proxy and a volume mount would have taken an evening, and it would still be running today without me thinking about it once
The media server was the excuse, not the point. What I wanted was a machine where the answer to “what is running here” is a Git repo, not my memory of what I docker run-ed eight months ago. Every service declared, every change a commit, and a rebuild path that doesn’t depend on me remembering anything.
That part worked. Six months in, I can rebuild my server from a repo URL. Mostly, but we’ll get to that. Everything between here and there is the rest of this post.
What? (The Stack)
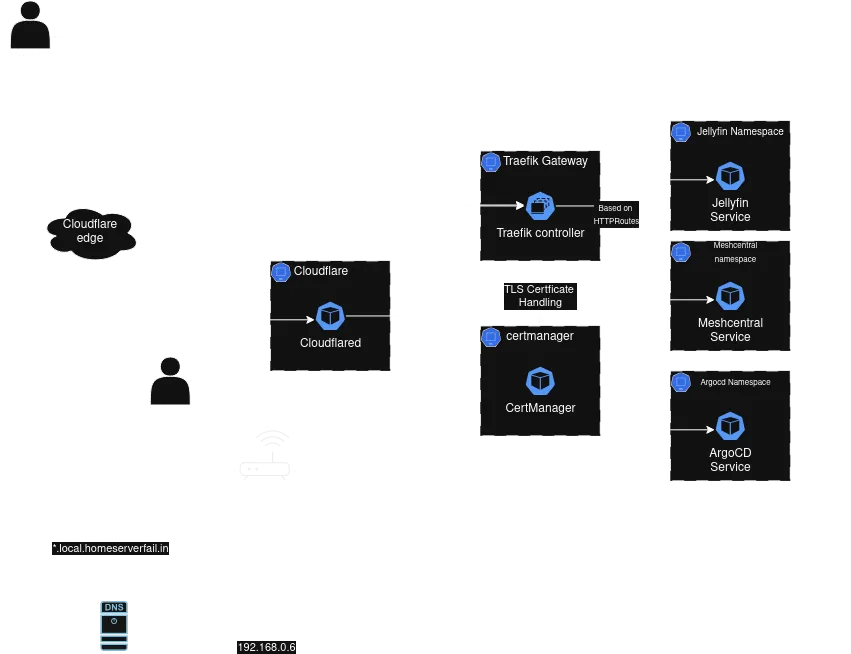
Before the story of how it got this way, here’s what’s actually on the machine. I’ve laid it out in the order a request travels: from your browser, through the tunnel, to the container serving the video.
Getting in from outside
I didn’t want the hassle of opening router ports or paying for a static IP just to reach my apps from outside. So i used Cloudflare Tunnels (cloudflared) plus Traefik as a Gateway controller for the Kubernetes Gateway API.
cloudflared runs inside the cluster and dials out to Cloudflare, holding that connection open. When someone requests jellyfin.homeserverfail.in, Cloudflare accepts it at their edge and pushes it back down that connection. The traffic arrives as a reply to a request my own machine made, which every home router is happy to allow. (I run it as a StatefulSet; a Deployment works just as well, a leftover from my initial manifest.)
The catch is that by default, this is the only route. A laptop two metres from the server still round-trips to the nearest Cloudflare PoP, burning WAN latency and upstream bandwidth on every byte, the difference between instant playback and buffering for direct-play 1080p.
Ideally I’d point a DNS record on my router at the LoadBalancer IP, but mine doesn’t support that. Instead, a wildcard *.local.homeserverfail.in in public DNS points at the server’s LAN address, so in-network clients resolve straight to the box.
Getting to the right place
Before starting let me explain why i chose gateway API instead of the trusty ol kubernetes ingress. Mostly because it makes switching controllers easy. With Ingress, anything beyond basic routing (redirects, header matching, TLS options) lives in controller-specific annotations, so moving from Traefik to something else means rewriting them. Gateway API makes those features part of the standard, and splits the setup into pieces (the Gateway itself, and the routes attached to it) that are each defined in code.
There are two ways to do this. The simple one: point cloudflared straight at each application’s service URL, e.g. jellyfin-service.jellyfin.svc.cluster.local, and call it a day. The other: point the tunnel at a gateway and let it do the routing. cloudflared preserves the original Host header, so a request for jellyfin.homeserverfail.in reaches Traefik with that hostname intact and the matching HTTPRoute picks it up. I add each hostname to the tunnel explicitly and send them all to the same gateway service, slightly more config than a catch-all, but nothing routes into the cluster unless I’ve listed it.
My initial manifests had no gateway or ingress controller; it seemed like maintenance I didn’t need. What changed my mind was realising I had no control over traffic once it entered the cluster. If I want SSO in front of these apps, something has to sit between cloudflared and the service to enforce it, and with a direct tunnel-to-service mapping, there’s nowhere to put it.
So basically this is the flow of traffic for my services:
I do plan on implementing a service mesh too in the near future to secure inter deployment/pod networking, tho it has its additional benefits which i ll talk about later.
What keeps it running
Before getting to where a request ends up, here’s what everything sits on: the cluster itself, and the tools running in the background that handle the nitty gritty.
The cluster
The cluster runs on K3s, after a stint on kind (Kubernetes IN Docker, bascially a multi node kubernetes cluster in docker where each node is a docker container)that I’ll get to in the How section. K3s is a certified Kubernetes distribution that ships as a single binary, and it comes with batteries included: Traefik, ServiceLB for LoadBalancer IPs, a local-path storage provisioner, and SQLite in place of etcd. Tho to be fair, I disabled the bundled Traefik (--disable=traefik). K3s installs it from its own manifests outside Argo CD, and I wanted the repo to be the end-all, be-all for redeployment, so Traefik gets deployed from Git like everything else.
A few notes about the laptop:
- Storage: The laptop has two drives, a 2 TB SSD and a 1 TB HDD. The SSD holds everything that benefits from fast reads and writes: video and app configs. The HDD gets what doesn’t care about speed, like books and backups. Rather than handing whole disks to the cluster, I expose specific folders from each through local-path volumes. Ideally this would be something like NFS, so a second node could reach the same data, but that needs a second machine, and right now I’m broke with exactly one laptop ૮(˶╥︿╥)ა
- GPUs: I started out trying to transcode on the GTX 1050, but I could never get transcoding to work reliably, and the 1050 isn’t a great transcoding card to begin with. Then it clicked that the laptop also has an Intel iGPU, and Quick Sync needs no proprietary driver at all. Jellyfin now transcodes on the iGPU, and the 1050 is free for work that actually wants CUDA.
The platform layer
None of these touch a request on its way to Jellyfin, but they’re the reason the cluster is a Git repo and not a pile of commands I ran once and forgot. They’re also where most of the DevSecOps learning happened.
Argo CD: GitOps. Argo CD watches the repo and makes the cluster match it. I push a commit, and it applies the change. If I edit something by hand with kubectl, it notices the drift and puts it back. Why ArgoCD? cause i had seen it being used in my previous workplace, and didnt know anything better
Sealed Secrets: GitOps means everything goes into Git, including passwords and API tokens, which is a problem. The usual answer is an external secret store, but a managed one like GCP Secret Manager costs money, and self-hosting HashiCorp Vault is one more thing to run and break. Sealed Secrets keeps it all in the repo instead: the controller in the cluster holds a private key, and anyone with the public key can encrypt a secret, but only the cluster can decrypt it. The repo can be read by anyone without leaking anything.
The catch: if the cluster dies and the private key dies with it, every sealed secret in the repo becomes permanently unreadable. So there are two things still on my list:
- Key rotation: The controller already generates a new sealing key every 30 days and keeps the old ones. What I still need to sort out is re-sealing existing secrets with the newest key, and a plan for rotating the secrets themselves if a key ever leaks.
- Backups: Right now I back up the keys manually. Since new ones keep appearing, that needs to become an automated backup of every key to somewhere secure.
cert-manager: Issues and renews TLS certificates for the Gateways. I use a Let’s Encrypt issuer with the DNS-01 challenge: since my domain’s DNS is on Cloudflare, cert-manager proves ownership by creating a TXT record through Cloudflare’s API. That’s also the only way to get a wildcard like *.local.homeserverfail.in. This is the part I mentioned earlier: enforcing TLS is easy, and renewal is the hard part. cert-manager is what makes renewal someone else’s problem.
CloudNativePG: The shared Postgres for everything that needs a real database. Jellyfin sticks to SQLite, but MeshCentral uses it today, and Authentik will once I set it up. Backups are still on the to-do list. The data sits on persistent volumes, so it survives pod restarts, but that’s durability, not a backup: it’s all on the same disk as everything else.
MeshCentral: Agent-based remote access to, well, the laptop itself, though it can manage other devices too. Not strictly required, but hella useful when your laptop’s screen is actually dying. The obvious irony: it runs on the cluster, so the moment the cluster breaks, the tool I’d use to fix it goes down with it. of course the question arises, what to do when the cluster is down… the answer is suffer the dying screen till the cluster is up (for now). ideally in future i would move this into a separate server/VPS in a different region/place to ensure availability. Yes, that’s a monthly bill, but a much smaller one for something that actually needs to live off the box.
Like everything else, it’s only reachable through the Cloudflare tunnel, or on the LAN through the *.local subdomain, and all traffic between the agents and the server is HTTPS. That leaves authentication as the main risk, and it’s a big one: MeshCentral gives full remote control of every machine running its agent. For now, logging in takes a username and password plus a second factor: either a TOTP code from Google Authenticator or a passkey stored in Bitwarden. SSO is on the list, but my laziness has been getting the better of me.
What’s actually running
Now on to the meat and potatoes: what’s actually running on the cluster. And oh boy, there’s a lot of it. It splits roughly into media, everyday apps, and the platform tools from the previous section.
Media
- Jellyfin: the media server itself
- Seerr (formerly Jellyseerr): lets people request movies and shows
- Sonarr: manages the TV library
- Radarr: manages the movie library
- Lidarr: manages the music library
- Tracearr: playback stats for Jellyfin
Everyday apps
- Vaultwarden: self-hosted Bitwarden-compatible password manager
- Mealie: recipe manager
- BentoPDF: PDF editing
Platform
Argo CD, Sealed Secrets, cert-manager, CloudNativePG and MeshCentral, covered above, plus Traefik as the Gateway controller and cloudflared for the tunnel.
How? (The Journey)
Everything above is the end state. This is how it actually got there, roughly in order, including the parts I’d rather not admit to.
Phase 1: you can certainly try.
This was the step i tested and learned how to deploy and configure some of the main tools, tools like Cloudflared, Jellyfin and Vaultwarden. This step didnt even have proper yaml files as most tests were in docker, where i checked how to configure the tunnel, how jellyfin and vaultwarden can be exposed through the tunnel, etc.
Application List (on docker):
- Jellyfin
- Vaultwarden
- Cloudflared
Phase 2: kubectl apply and hope it works
Next was a handful of INDIVIDUAL YAML files and kubectl apply -f, on kind. by this point i had learnt difference between deployment, statefulset, daemonset and pods. so Jellyfin got a Deployment, a Service and a volume, and cloudflared statefulset pointed straight at the Jellyfin Service, with no gateway in between, and each app was in their own Namespace.
And it worked. Mostly. The first real lesson was that storage was not only meant for the media, it is meant also for the config, as when the pod restarts if the config is not persistent the admin creds, and the settings configured will have to be done again and again. With a few people streaming, direct play slowed significantly, and kind was never meant to carry that. Second lesson was that this was definitly not ready for public exposure. due to secrets laying around in the repo in plain text.
The Quiter and long term problem was: deployment was tedious and a nightmare, i had to manually ensure that all files are applied and when it is time to delete again manually remove all. This led me to actually learn best practices and automation methods
Application List (on kind):
- Jellyfin
- Vaultwarden
- Cloudflared
Phase 3: Learn Best practices

This is the phase where i learnt about kustomize and oh boy was it a boon for multi resource deployments. i started adding more applications to be hosted, to assist jellyfin. in addition to that i added a network policy not allowing traffic to not allow traffic from the jellyfin namespace to vaultwarden namespace just as a safety precaution.
The issues i faced were fun and annoying at the same time:
- This was the phase where i messed up for a while in terms of resource placement in code. i tried multiple variants where initially every resource pertaining to a single application was in a single file, when that got tedious i changed to resource based file creation i.e. all PVs in a single file, every deployment in another, so on so forth. Both of these methods were tiring for different reasons. the first in terms of searching for a specific error and second in terms of formatting and linting.
- during this stage only i moved secrets into a separate Configmap initially and later on to secrets, still using the basic secrets with no additional encryption.
- Since all media were in the HDD instead of the SSD, and there was no transcoding the media streaming was slow. i didnt work on this issue for a while as i was still using kind, and i knew that could be one of the reason (turns out it was a reason the other was the HDD itself)
- I couldnt work on my server remotely, like when i was in work or away from my server laptop.
- I couldnt access Sonarr for some reason. tried changing ports protocols (HTTP -> HTTPS and back) still nothing
So improvements required as of this stage were:
- additional encryption to secrets,
- a proper restructuring of resources and automated deployment instead of manual deployment each time.
- Remote access to the server
- Faster Storage for media
- resolve the sonnar access issue
Application List (on kind):
- Jellyfin
- Sonarr
- Radarr
- Lidarr
- Vaultwarden
- Cloudflared
Phase 4: 2S - Stability and Speed

In this phase my main focus was stability and speed, and first on the list was getting off kind. kind was never the problem for deploying things. It was the problem for running them. Every stream took the scenic route: through Docker’s networking, through bind mounts into a container pretending to be a node, off a spinning HDD, and out through the tunnel. That’s not really kind’s fault. It’s built for throwaway test clusters, and I was asking it to be a 24/7 media server.
So I did what any (in?)sane person would do and jumped to kubeadm… Nah, still daunting. I landed on K3s instead, and installing it took one command: curl -sfL https://get.k3s.io | sh -, and lo and behold, I run Kubernetes. Then it was a matter of switching the persistent volumes from Docker-mounted paths to real folders on the host, and moving the media onto the SSD. Doing these changes helped a lot in speeding up streaming media. In addition the move to k3s also sped up the UI.
Then came the night from the intro: The cloudflared logs said connected. The Pods said running. The browser said Nice try.
Fixing it took “only” two to three hours, most of which I spent checking every component on its own, the way I’d work through a target on a pentest:
- cloudflared: Connected, no errors.
- Jellyfin: Working fine, waiting for requests.
Every piece worked on its own. Put together, nothing got through. That’s when it struck me: the laptop was running Arch, and the whole cluster was running on top of it. Could the host firewall be blocking this? It felt like a weird thing to suspect, because there was no traffic coming from outside the laptop. cloudflared was talking to to Jellyfin directly, all on the same machine.
It turns out “the same machine” doesn’t mean what I thought it meant. In K3s, traffic between Pods and Services doesn’t stay in some sealed box. It gets routed through the host’s own kernel, across virtual interfaces like cni0 and flannel.1. From the host’s point of view, that’s packets arriving on one interface and being forwarded out another, and ufw’s default policy for forwarded traffic is to drop it. Running ufw status verbose spells it out in the last line: deny (routed). That one word was the entire bug.
The fix was letting the cluster’s own address ranges through:
ufw allow 6443/tcp #apiserver
ufw allow from 10.42.0.0/16 to any #pods
ufw allow from 10.43.0.0/16 to any #services
Naturally, I found out afterwards that this is right there in the K3s docs, under the section I’d skipped.∘ ∘ ∘ ( °ヮ° ) ?. This was also the Phase where i setup Meshcentral, for remote access, this was required whenever i was away from my PC and needed to make some minor changes. Right after that i added my GPUs to the cluster, will add that portion as a separate post later as this is already too long.
Application List (on K3s):
- Jellyfin
- Sonarr
- Radarr
- Lidarr
- Vaultwarden
- Cloudflared
- Meshcentral
- BentoPDF
- Cloud Native PG
- Mealie
Phase 5: Restructuring
This was the point where the project stopped being “Jellyfin on Kubernetes” and became what I actually wanted: a server I could rebuild from Git. This is also kinda the most recent phase where i overhauled most of the cluster and the repo maintaining it. Why? because i can. So lets start from the beginning:
- First i restructured the repo to a more segregated folder structure, each application is a folder of itself, with all resources in a single file except the secrets(if any), held together using a kustomize with 2 overlays, one for stable cluster and other a testing cluster. The secrets are located in overlays so that each overlay can have a different secret if required, also helps in secrets encryption too.
- Next was image version pinning of every service for stability and easy remediation in case of future vulnerabilities
- ArgoCD Deployment, this was relatively easy as i just had to apply the kustomize provided by argocd
- Next came Actually using Argocd, And that is where the laziness hit, so instead of writing a Argo
applicationfor every App, i wrote aapplicationsetfor ones that have common deployment strategy, like everything related to Jellyfin was to be deployed in the same namespace or every infra related app required a separate namespace. Apps that required some special treatment like Traefik or argocd got their ownapplication - I added Sealed secrets and then encrypted all secrets using the same. I chose Sealed Secrets over SOPS because it needs nothing outside the cluster. SOPS needs a key managed somewhere else (age, PGP or a cloud KMS) and a plugin before Argo CD can decrypt anything. Sealed Secrets just needs its controller: secrets are encrypted with a public key that lives in the repo and decrypted with a private key that never leaves the cluster.
- Next was the actual Traefik setup, for this i removed the default traefik, added traefik via Argocd and chose gateway API over ingress, which required installation of gateway API CRDs.
- I made 2 httproutes for each of the application one for remote access and other for the in network access.
- The Traefik gateway has four listeners: HTTP and HTTPS for tunnel traffic, and HTTP and HTTPS for LAN traffic. The HTTP listeners exist only to redirect to HTTPS. Only the LAN listeners are exposed on the LoadBalancer IP, so the tunnel listeners are reachable solely from inside the cluster, by cloudflared.
- I also added certmanager so that the HTTPS listeners can have TLS certificates, that are issued by letsencrypt who validated my cloudflare DNS for the domain, (will explain in later post.)
My Current Repo looks as follows:
.
├── Applications
│   ├── Media Server
│   │   ├── JellyFin
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── jellyfin.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── JellySeer
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── jellyseer.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── Lidarr
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── lidarr.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── Radarr
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── radarr.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── Sonarr
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── secrets.yaml #temp file with no/dummy data
│   │   │   │   └── sonarr.yaml
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── Tracearr
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── secrets.yaml #temp file with no/dummy data
│   │   │   │   └── tracearr.yaml
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   ├── MgmtTools
│   │   ├── BentoPDF
│   │   │   ├── Bases
│   │   │   │   ├── bentopdf.yaml
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   ├── kustomization.yaml
│   │   │       │   └── secrets-patch.yaml
│   │   │       └── Testing
│   │   │           ├── kustomization.yaml
│   │   │           └── secrets-patch.yaml
│   │   ├── mealie
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── mealie.yaml
│   │   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           └── kustomization.yaml
│   │   ├── vaultwarden
│   │   │   ├── Bases
│   │   │   │   ├── httpRoute.yaml
│   │   │   │   ├── kustomization.yaml
│   │   │   │   ├── secrets.yaml #temp file with no/dummy data
│   │   │   │   └── vaultwarden.yaml
│   │   │   └── Overlays
│   │   │       ├── Stable
│   │   │       │   └── kustomization.yaml
│   │   │       └── Testing
│   │   │           ├── kustomization.yaml
│   │   │           └── secrets-patch.yaml
│   │   └── vscode
│   │       ├── Bases
│   │       │   ├── kustomization.yaml
│   │       │   ├── secrets.yaml #temp file with no/dummy data
│   │       │   └── vscode.yaml
│   │       └── Overlays
│   │           ├── Stable
│   │           │   └── kustomization.yaml
│   │           └── Testing
│   │               └── kustomization.yaml
│   └── service urls.txt
├── Argocd
│   ├── Application
│   │   ├── argocd-stable.yaml
│   │   ├── argocd-testing.yaml
│   │   ├── Traefik-stable.yaml
│   │   └── Traefik-Testing.yaml
│   ├── ApplicationSets
│   │   ├── Stable
│   │   │   ├── Infra.yaml
│   │   │   ├── managementTools.yaml
│   │   │   └── Media Server.yaml
│   │   └── Testing
│   │       ├── Infra.yaml
│   │       ├── managementTools.yaml
│   │       └── Media Server.yaml
│   └── Kustomization
│       ├── Bases
│       │   ├── httpRoute.yaml
│       │   ├── kustomization.yaml
│       │   └── namespaces.yaml
│       └── Overlays
│           ├── Stable
│           │   ├── kustomization.yaml
│           │   ├── secrets-patch.yaml
│           │   └── secrets.yaml
│           └── Testing
│               ├── kustomization.yaml
│               └── secrets-patch.yaml
├── GatewayAPICRD
│   └── kustomization.yaml
├── Infra
│   ├── certmanager
│   │   ├── Bases
│   │   │   ├── kustomization.yaml
│   │   │   └── namespace.yaml
│   │   └── Overlays
│   │       ├── Stable
│   │       │   └── kustomization.yaml
│   │       └── Testing
│   │           └── kustomization.yaml
│   ├── cloudflare
│   │   ├── Bases
│   │   │   ├── cloudflare.yaml
│   │   │   ├── kustomization.yaml
│   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   └── Overlays
│   │       ├── Stable
│   │       │   ├── kustomization.yaml
│   │       │   └── secrets-patch.yaml
│   │       └── Testing
│   │           ├── kustomization.yaml
│   │           └── secrets-patch.yaml
│   ├── meshcentral
│   │   ├── Bases
│   │   │   ├── configmap.yaml
│   │   │   ├── httpRoute.yaml
│   │   │   ├── kustomization.yaml
│   │   │   ├── meshcentral.yaml
│   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   └── Overlays
│   │       ├── Stable
│   │       │   ├── kustomization.yaml
│   │       │   └── secrets-patch.yaml
│   │       └── Testing
│   │           ├── kustomization.yaml
│   │           └── secrets-patch.yaml
│   ├── postgres
│   │   ├── Bases
│   │   │   ├── clusterCRD.yaml
│   │   │   ├── kustomization.yaml
│   │   │   └── secrets.yaml #temp file with no/dummy data
│   │   └── Overlays
│   │       ├── Stable
│   │       │   ├── kustomization.yaml
│   │       │   └── secrets-patch.yaml
│   │       └── Testing
│   │           ├── kustomization.yaml
│   │           └── secrets-patch.yaml
│   └── SealedSecrets
│       ├── Bases
│       │   └── kustomization.yaml
│       └── Overlays
│           ├── Stable
│           │   └── kustomization.yaml
│           └── Testing
│               └── kustomization.yaml
├── infraHelm
│   ├── Authentik
│   │   ├── Stable
│   │   │   └── values.yaml
│   │   └── Testing
│   │       └── values.yaml
│   └── Traefik
│       └── values.yaml
├── kind-config.yml
├── meshcentralConfig.json
├── mightberequired.yaml
├── README.md
└── traefik
    ├── Bases
    │   ├── Certificate.yaml
    │   ├── httpRoute.yaml
    │   ├── Issuer.yaml
    │   ├── kustomization.yaml
    │   └── secrets.yaml
    └── Overlays
        ├── Stable
        │   ├── kustomization.yaml
        │   └── secrets-patch.yaml
        └── Testing
            ├── kustomization.yaml
            └── secrets-patch.yaml
Application List (on K3s):
- Jellyfin
- Sonarr
- Radarr
- Lidarr
- Vaultwarden
- Cloudflared
- Meshcentral
- BentoPDF
- Cloud Native PG
- Mealie
- ArgoCD
- Traefik
- Sealed Secrets
- Cert Manager
The End?
Which brings us back to the start: the first stretch of 2-3 weeks in about six months that nothing crashed and nothing went unreachable. The cluster is a Git repo, every service is behind Traefik with real certificates, and if the disk dies I can rebuild it. Mostly. The “mostly” is the backups, which is exactly where the future will lead to, in addition to additional security features like SSO, and automations for security and configurations, and finally more useful applications. I could try adding fun/useful services, will update where required.
What’s next
- Authentik for SSO
- A service mesh for pod-to-pod traffic
- Automated backups for CloudNativePG and the Sealed Secrets keys
- NFS (or similar) once there’s a second machine
- Moving MeshCentral off the laptop
- A small LLM or Blender renders on the GTX 1050
- Seed initial users for every service, so a rebuild doesn’t mean recreating accounts by hand (ultra not important)
LLM Usage Disclosure:
I Believe in being upfront about this, so here’s how this post was written.
What’s mine: the project itself, every decision in the cluster, every failure and fix described here, and the first draft of every section. The six months of broken nights were very much human-made.
Where I used an LLM: I used Claude (by Anthropic) as an reviewer. It:
- reviewed drafts and pointed out contradictions, gaps and loose threads.
- suggested how to structure sections, like splitting a larger chunk of text to more compact seperate sub headings for better clarity.
- suggested paragraph rewrites for for clarity, including a few technical explanations.
- fact-checked technical details, such as how ufw handles forwarded traffic and how Sealed Secrets rotates its keys.
What I checked: every technical claim and command was verified against my own setup before publishing. If something here is wrong, that’s on me, not the tool.